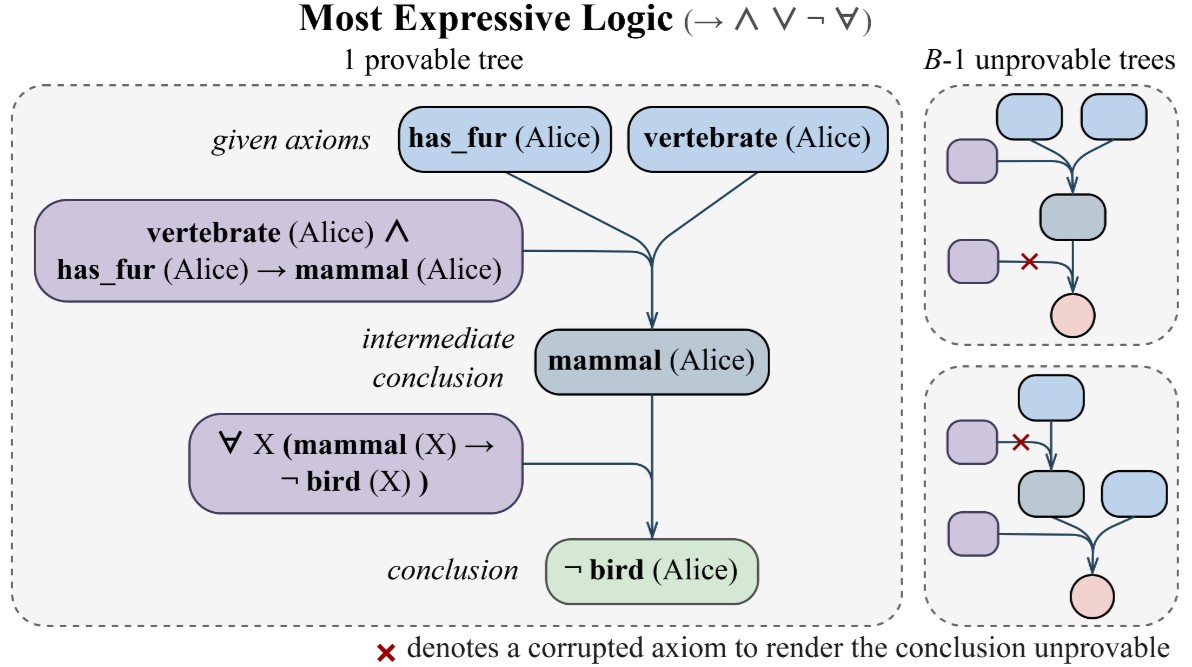
How Deep Can LLMs Learn to Reason? Expressiveness Is Key
A synthetic logical reasoning environment for studying RL scaling and transfer in long-horizon reasoning.
I am a Ph.D. student at Purdue University, advised by Prof. Abulhair Saparov. Previously, I received my M.S. from UC San Diego, advised by Prof. Jingbo Shang, and my B.E. from Shanghai Jiao Tong University, where I was part of the ACM Honors Class.
My research focuses on reasoning and planning in large language models. In particular, I explore how reinforcement learning during post-training can improve the reasoning capabilities of foundation models.
A synthetic logical reasoning environment for studying RL scaling and transfer in long-horizon reasoning.
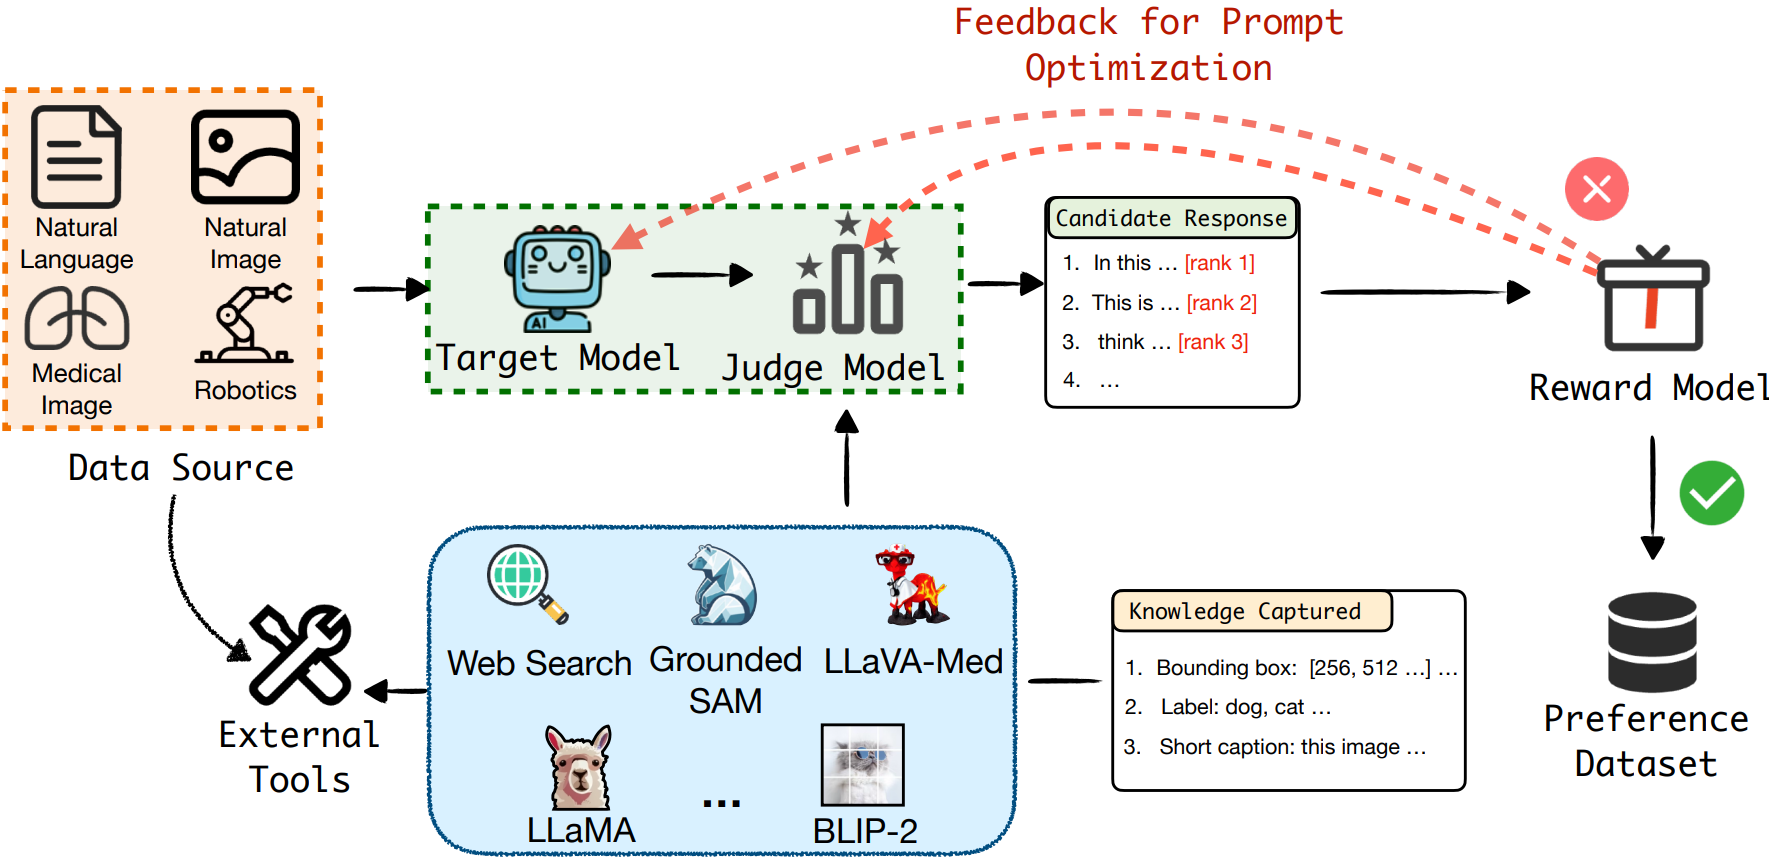
An automatic framework for synthesizing high-quality preference data for language model training.
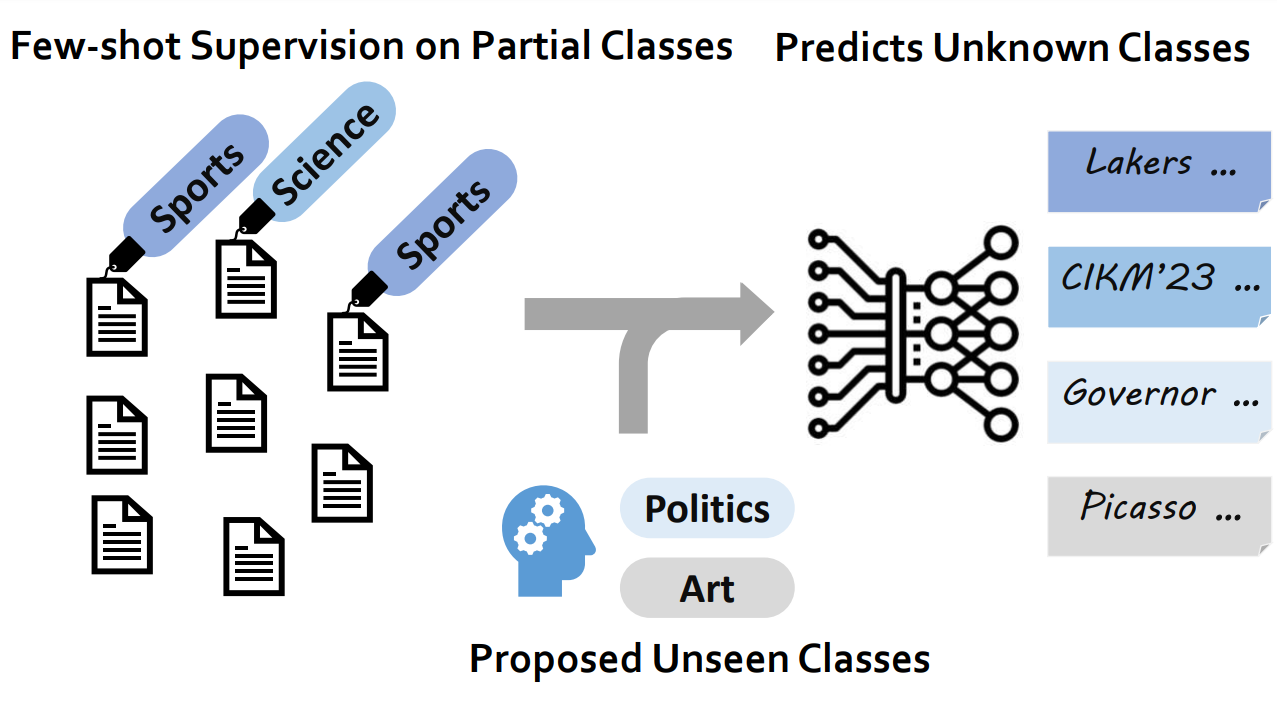
Weakly supervised text classification in an open world, where the full set of classes is not known in advance.
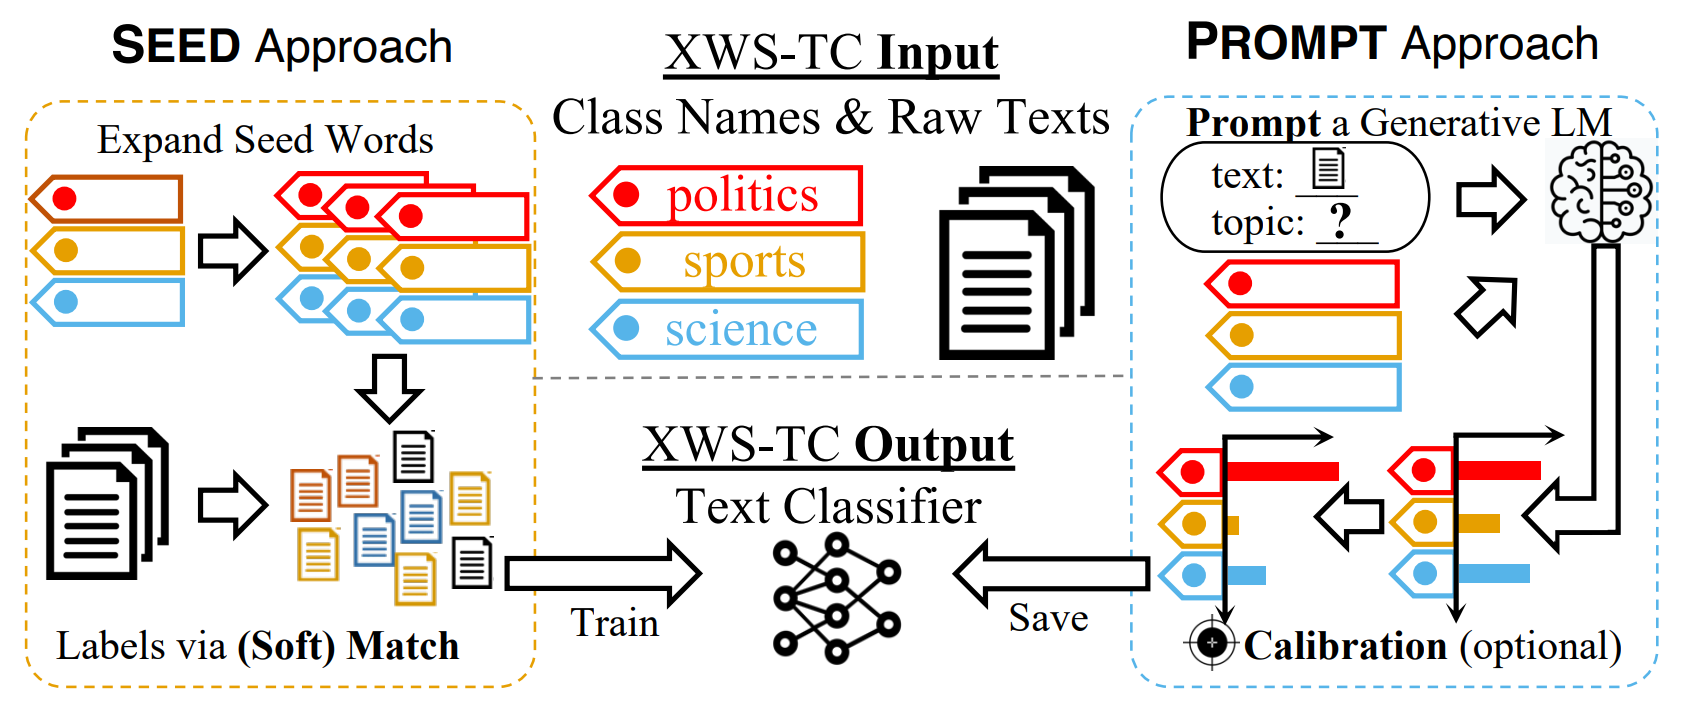
A benchmark comparing seed-matching and prompting approaches under extremely weak text supervision.
* Equal contribution